Hook
Employees often ask the same questions about HR policies, contracts, pricing, product documents, or technical manuals. Yet the answers remain scattered across SharePoint, PDFs, cloud drives, databases, and internal wikis, making simple information difficult to find quickly.
Introduction
A Retrieval-Augmented Generation (RAG) system connects an LLM with a company’s internal knowledge. It retrieves relevant company information and uses it as context to generate grounded answers.
Building one requires more than connecting documents to an AI model. Companies also need clean data, effective retrieval, access controls, testing, monitoring, and regular updates.
Key Takeaways
Here is a quick look at the main things you will learn in this guide:
- How to identify useful internal knowledge for RAG.
- How to clean, structure, chunk, and index company documents.
- How vector, keyword, hybrid search, metadata, and reranking work.
- How to protect restricted company information.
- How to test, monitor, and update the system.
Table of Contents
- Define What Your Company RAG System Must Answer
- Audit and Prepare Your Internal Knowledge
- Choose the Right Data Sources and Retrieval Architecture
- Clean and Structure Company Documents Before Indexing
- Chunk Internal Documents for Better Retrieval
- Create Embeddings and Build the Knowledge Index
- Combine Keyword, Vector and Hybrid Search
- Connect Retrieved Knowledge to the LLM
- Protect Internal Data With Access Controls
- Test RAG Accuracy Before Going Live
- Monitor Answers, Costs and Knowledge Updates
- Move From Prototype to a Production RAG System
Define What Your Company RAG System Must Answer
Start with the questions employees need answered most often. These may involve HR policies, technical documents, contracts, product information, pricing, or compliance records.
Define the users and knowledge scope at the same time. This helps determine the required sources, permissions, retrieval rules, and testing criteria.
Audit and Prepare Your Internal Knowledge
List every source containing relevant company information before building the retrieval layer. Include document repositories, databases, wikis, cloud storage, and business systems.
Review each source for accuracy and relevance. Remove outdated files, duplicates, conflicting versions, and content without clear ownership.
Map Data Sources
List SharePoint, cloud drives, wikis, databases, CRM systems, and document repositories.
Remove Outdated Content
Archive old policies, procedures, manuals, and superseded versions.
Classify Sensitive Data
Separate internal, confidential, financial, employee, customer, and restricted information.
Assign Content Owners
Identify who reviews and updates each important knowledge source.
Choose the Right Data Sources and Retrieval Architecture
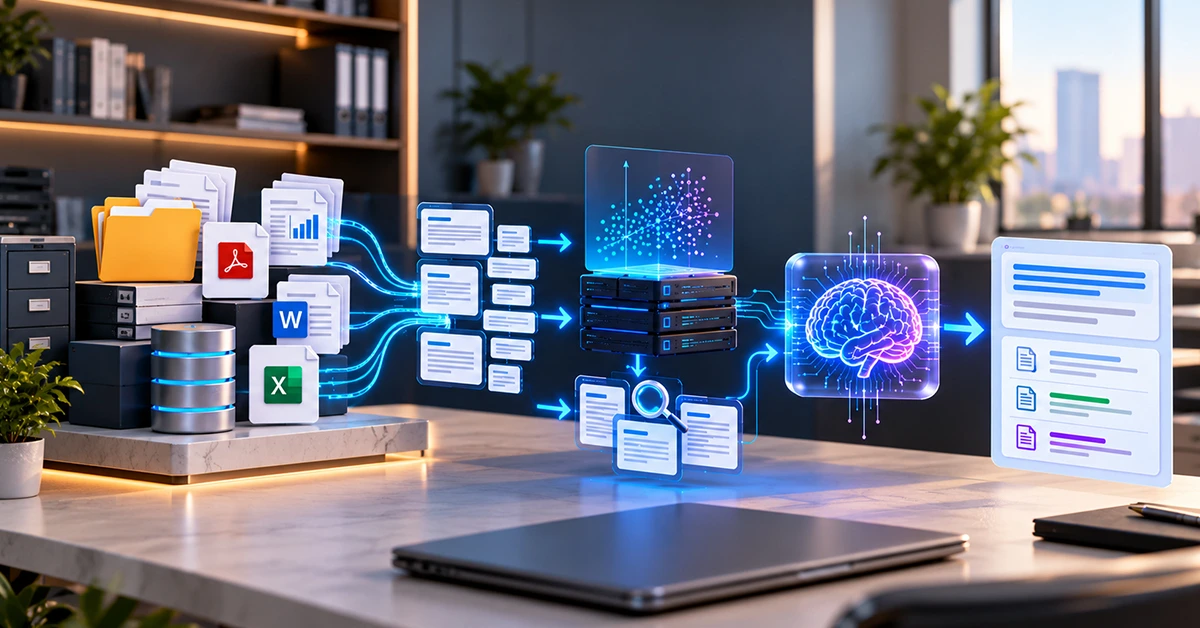
A typical RAG flow moves from data ingestion to processing, chunking, embeddings, indexing, retrieval, and answer generation.
Choose the architecture based on data volume, document types, update frequency, security needs, and query volume.
Clean and Structure Company Documents Before Indexing
Raw files often contain repeated headers, broken tables, duplicate text, and irrelevant formatting. Clean these elements before indexing. Preserve titles, headings, dates, versions, authors, departments, and source locations because they provide useful retrieval context.
- Remove Repeated Text: Delete unnecessary headers and footers.
- Preserve Structure: Keep headings and section relationships.
- Process Tables: Extract table information accurately.
- Keep Document Details: Retain titles, dates, and versions.
- Record Ownership: Store authors and responsible teams.
- Save Source Locations: Keep links or identifiers for original documents.
Chunk Internal Documents for Better Retrieval
Chunking divides large documents into smaller searchable sections. Each chunk should contain enough context while staying focused. Use document structure to guide chunking. Policies, contracts, manuals, FAQs, and reports may require different chunking methods.
Keep Related Information Together
Keep connected requirements, definitions, exceptions, and explanations in the same chunk.
Follow Document Structure
Use headings, paragraphs, tables, and logical sections as boundaries.
Add Chunk Metadata
Store the document name, department, date, version, category, and access information.
Test Chunk Size
Compare different chunk sizes and overlap settings before selecting the final approach.
Create Embeddings and Build the Knowledge Index
Embeddings convert text into numerical representations that help the system find semantically related content.
Store embeddings with metadata and source references so retrieved information can connect back to its original document.
- Choose an Embedding Model: Match the model to your content and language needs.
- Generate Embeddings: Create vectors for approved document chunks.
- Store Metadata: Attach relevant attributes to each chunk.
- Keep Source IDs: Preserve document and section references.
- Track Versions: Record the current document version.
- Re-index Changes: Update the index when approved content changes.
Combine Keyword, Vector and Hybrid Search
Vector search finds content based on meaning, while keyword search handles exact terms. Both can be useful for internal company information. Hybrid search combines these approaches, while reranking can prioritize the most relevant results before they reach the LLM.
Use Vector Search
Find semantically similar information despite different wording.
Use Keyword Search
Find exact names, codes, identifiers, and technical terms.
Apply Metadata Filters
Filter results by department, date, document type, region, or version.
Rerank Results
Reorder retrieved passages based on their relevance to the question.
Connect Retrieved Knowledge to the LLM
The system sends relevant retrieved passages to the LLM as context. The model then uses this information to generate the response. Set clear instructions for using sources and handling missing information. This helps reduce unsupported answers.
- Pass Relevant Context: Send only useful retrieved content.
- Use Company Sources: Instruct the model to rely on supplied evidence.
- Avoid Unsupported Claims: Tell it not to invent missing information.
- Handle Conflicts: Define how conflicting sources should be treated.
- Include Citations: Provide document or source references.
- Set Response Rules: Use a consistent answer format.
Protect Internal Data With Access Controls
Internal RAG systems may contain confidential employee, financial, customer, contract, and business information. Retrieval must follow existing data permissions. Check authorization before restricted content reaches the LLM. User identity, document permissions, and retrieval filters should work together.
Connect User Identity
Use the company’s identity system to identify the requesting user.
Store Access Rules
Associate documents and chunks with approved users, groups, or roles.
Filter Retrieved Content
Remove unauthorized content before sending results to the LLM.
Maintain Access Logs
Record relevant access and retrieval events for security review.
Test RAG Accuracy Before Going Live
A fluent answer does not prove that retrieval worked correctly. Test the retrieved content and generated answer separately. Build a test set from real company questions and include difficult, ambiguous, restricted, and unanswerable queries.
- Test Common Questions: Use frequently asked employee queries.
- Check Retrieval: Verify that relevant passages appear.
- Verify Answers: Compare responses with source documents.
- Check Citations: Confirm that sources support the answers.
- Test Conflicts: Include outdated or conflicting information.
- Test Restrictions: Check unauthorized and unanswered queries.
Monitor Answers, Costs and Knowledge Updates
RAG systems need continuous monitoring because company content, query patterns, and model usage change over time. Track answer quality, retrieval failures, costs, response times, outdated content, and user feedback.
Track Retrieval Failures
Review irrelevant, incomplete, or outdated results.
Monitor System Costs
Track embedding, storage, search, model, and infrastructure costs.
Detect Knowledge Changes
Monitor document versions, dates, and updates requiring re-indexing.
Review User Feedback
Use feedback to identify missing information and recurring problems.
Move From Prototype to a Production RAG System
Start with one knowledge area and a limited user group. Validate quality, security, speed, and costs before expanding. Document ownership and operating procedures so the system remains manageable as data and users increase.
- Start Small: Begin with one high-value knowledge area.
- Validate Security: Check permissions before wider access.
- Maintain Test Questions: Keep a permanent evaluation set.
- Expand Gradually: Add data sources in controlled stages.
- Document Settings: Record indexing and retrieval configurations.
- Review Regularly: Establish a process for updates and evaluation.
Conclusion
A reliable company RAG system depends on clean knowledge, effective retrieval, accurate context, and strong access controls. Connecting documents to an LLM alone does not ensure useful or reliable answers.
Start with a focused use case, test each stage, and keep internal knowledge current. Regular monitoring, evaluation, and updates help maintain answer quality as the system grows.
FAQs
What is a RAG system for company knowledge?
A RAG system retrieves relevant information from internal company sources and gives that information to an LLM as context for generating an answer.
What company data can a RAG system use?
It can use documents, policies, manuals, knowledge bases, databases, support records, contracts, reports, and other structured or unstructured internal sources.
Does company data need to be used for model training?
No. RAG can connect an LLM to external knowledge at query time instead of retraining the model whenever company information changes.
How do you prevent employees from seeing restricted documents?
Use authentication, authorization, document-level permissions, and query-time security filters so retrieval only returns information the user can access.
Is vector search enough for internal company data?
Not always. Hybrid retrieval can combine semantic vector search with keyword matching, which helps with exact names, codes, technical terms, and policy references.
How do you know if a RAG system is accurate?
Test it against representative questions and evaluate retrieval quality, answer grounding, citations, access controls, latency, and cost.
Explore More
- How to Control AI Agents That Can Take Actions Across Business Systems
- How to Measure AI Agent Accuracy, Cost and Task Completion in Production
- How to Manage Multiple AI Agents Across Different Business Functions
Keep following us for more guides and updates.